ODBC Azure Blob Driver for JSON Files
Query JSON blobs from Azure Blob Storage.
Query JSON files stored in Azure Blob Storage containers with plain SQL. Connect with your Account Key, SAS or Azure AD, read one file or a wildcard set including GZip / Zip files, and use the data in SQL Server (T-SQL) or your BI, ETL and reporting tools, all without writing code.
Included in the Professional edition and above
- Any ODBC-compliant tool
- Runs in your environment
- SQL Server via Data Gateway
- 32-bit and 64-bit


At a glance
What the Azure Blob Driver for JSON Files can do
Query JSON blobs from Azure Blob Storage.
JSON files in Azure Blob
Query JSON files stored on Azure Blob Storage containers as tables, without downloading them first.
- Connect with Account Name and Account Key (or SAS / Azure AD)
- Single file or wildcard
- Sub-folders with
RECURSIVE
Compressed files
Read GZip and Zip compressed files with the FileCompressionType option.
- None, Zip or GZip
- Wildcards across archives
- Same SQL
Familiar SQL
Use WHERE, ORDER BY, GROUP BY and built-in math, string, date and JSON functions on top of the data source.
- Standard SELECT syntax
- Custom functions in the SQL dialect
- Driver options in a WITH clause
Works with the tools you have
Any ODBC-compliant tool can use the DSN: Power BI, Tableau, Qlik, SSRS, Informatica, Excel and SSIS.
- Create a DSN once, reuse it everywhere
- 32-bit and 64-bit ODBC
- Stored in the standard ODBC Data Source Administrator
Use it from code
Connect from Java, C#, Python, PowerShell and more with an ODBC connection string that names the DSN.
- Standard ODBC connection strings
- Parameterized queries
- Same SQL as in the UI
SQL Server via Data Gateway
Query the driver from SQL Server (linked server / OPENQUERY) without installing it on the SQL Server machine, through the Data Gateway.
- No driver install on the server
- Works with SQL Server 2012 through 2025 (32/64 bit)
- Same DSN, same SQL
See all features
- Read JSON files from Azure Blob Container using familiar SQL Query language
- Integrate insight any ODBC Compliant Reporting / ETL tools (e.g. Power BI, Tableau, Qlik, SSRS, Informatica, Excel, SSIS)
- Support for programming languages such as JAVA, C#, Python, PowerShell and more…
- Tight integration with Microsoft SQL Server (With support for Gateway Option – No need to install Driver on Server)
- Familiar SQL Query language support including WHERE, ORDER BY, GROUP BY constructs
- Support for custom math/ string / datetime / JSON functions in SQL query Language
- Support for Array Flattening and Complex Transformations for 2D arrays (See this article )
- Read single or multiple files (wildcard pattern supported e.g. *.json)
- Support for reading Zip and Gzip compressed files (stream mode)
- Support missing columns at the end (Auto fill with null values)
- Option to pivot data (transform columns into rows)
SQL Server 2012–2025
Ways to use it
Pick how you reach your data.
Configure the DSN once, then query it from any ODBC tool or from SQL Server.
Query one JSON file.
Set SRC to the path of a file in your container.
- Credentials: Account Name and Account Key (or SAS / Azure AD)
- SQL on top of the file
- Preview in the UI
Query many JSON files at once.
Use a wildcard such as customers*.???, add RECURSIVE for sub-folders and read GZip or Zip files.
- Wildcard patterns
- Sub-folders with RECURSIVE
- GZip / Zip
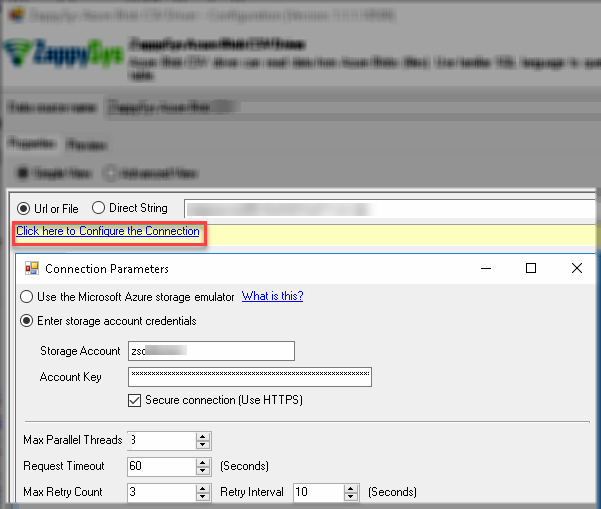
Query it from SQL Server with Data Gateway.
Expose the driver through the ODBC PowerPack Data Gateway and create a linked server in SQL Server. The driver does not have to be installed on the SQL Server machine.
- Linked server or OPENQUERY
- No driver install on the server
- Works with SQL Server 2012 through 2025 (32/64 bit)
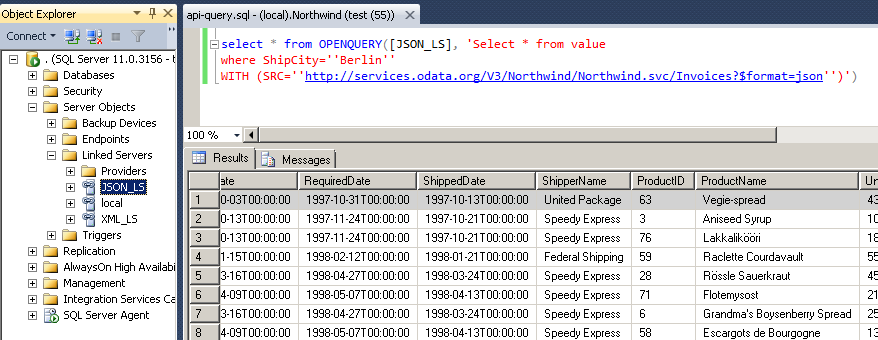
Inside the UI
The driver UI, step by step.
Real screens from the ZappySys ODBC driver configuration.
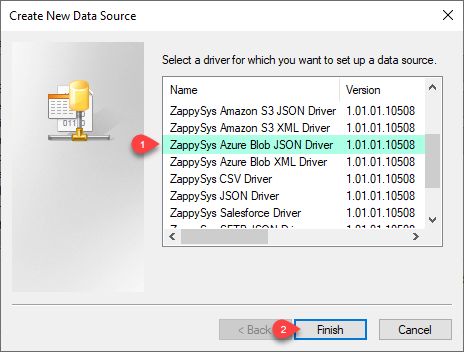
Create the DSN
Add a user or system DSN and pick the Azure Blob Driver for JSON Files.
SQL example
Write SQL. Get a flat table.
The driver reads files in Azure Blob Storage containers, flattens the JSON and lets you use WHERE, ORDER BY, GROUP BY and functions on top. Below: a sample document, the SQL query and the rows it returns.
-
Sample JSON data
A JSON file in your container, shown here as a sample.
{ "Customers": [ { "CustomerID": "C1", "CompanyName": "Company 1", "City": "Atlanta" }, { "CustomerID": "C2", "CompanyName": "Company 2", "City": "Boston" }, { "CustomerID": "C3", "CompanyName": "Company 3", "City": "Atlanta" } ] } -
Run the SQL query
SQL Query
SELECT CustomerID, CompanyName FROM $ WHERE City = 'Atlanta' ORDER BY CompanyName WITH ( SRC = 'Northwind-Container/customers*.json', Filter = '$.Customers[*]' )Paste the statement into the driver’s Query Editor, or run it from any ODBC tool or language.
WITH (…) clause carries driver options, so a single DSN can read many sources.
-
Rows returned to your tool
CustomerID CompanyName C1 Company 1 C3 Company 3 Connect Power BI, Excel, SSIS, Python or SQL Server to the DSN to get the same rows.
Illustrative input and output. More query samples are in the online help.
SQL query examples
Copy a query, change the source, run it.
13 of the 30 examples from the Azure Blob Driver for JSON Files help. Open one to see the SQL.
Read files, API responses and objects as rows.
Query Single File
This example shows how to query single JSON file (For multiple file use wildcard (i.e. *.json)). This example selects root level hierarchy (i.e $ as table name). Use table selector from toolbar to exact data from different hierarchy (i.e table).
SELECT * FROM $ WITH (SRC='zappysys-public-bucket/cust-1.json')Query Multiple Files
This example shows how to query multiple JSON files using wildcard (i.e. *.json). This example selects root level hierarchy (i.e $ as table name). Use table selector from toolbar to exact data from different hierarchy (i.e table).
SELECT * FROM $
WITH (
    SRC='zappysys-public-bucket/cust*-?.json'
    --,RECURSIVE='True' --Include files from sub folder
)Query direct JSON string (embedded inside query)
This example shows how to query direct JSON string embedded inside query. This is useful for testing purpose. In real world this may not be the case because data may be coming from File or URL (API call).
SELECT * FROM rows
WITH
(DATA='
{
  rows : [
        {id:1, name: "AAA"},
        {id:2, name: "BBB"},
        {id:3, name: "CCC"}
  ]
}'
)Query with static Metadata (META option / Override Mode)
This example shows how to supply custom Metadata rather than relying dynamic metadata detection (based on 300 rows scanning). If you run query you can click on [View Metadata] button to generate default metadata.
SELECT * FROM rows
WITH
(DATA='
{
  rows : [
        {id:1, checknumber:"0001", name: "AAA"},
        {id:2, checknumber:"0002", name: "BBB"},
        {id:3, checknumber:"0003", name: "CCC"}
  ]
}'
--//Method-1: >>>DIRECT META (compact mode)<<<
,META='id:int;checknumber:string(10);name:string(10)'
-- Add: @OverrideMode:1 in the column list to override meta for only specific column(s) - In below example we are changing default datatype/length for id and checknumber, all other columns are dynamic so dont have to supply in META clause
--,META='@OverrideMode:1;id:int;checknumber:string(10)'

--//Method-2: >>>DIRECT META (json mode)<<<
--,META='[{Name:"id",Type:"Int32"},{Name:"checknumber",Type:"String",Length:10},{Name:"name",Type:"String",Length:10}]'
-- Add: @OverrideMode entry in the column list to override meta for only specific column(s). No need to set Type for that entry - In below example we are changing default datatype/length for id and checknumber, all other columns are dynamic so dont have to supply in META clause
--,META='[{Name:"@OverrideMode"}, {Name:"id",Type:"Int32"},{Name:"checknumber",Type:"String",Length:10}]'

--//Method-3: >>>META from File <<<
--,META='c:/data/meta.json'

--//Method-4: >>>META from Internal Storage - Just refer entry by name <<<
--,META='MY_META_STORAGE_NAME'

)Escape Sequence (String Literals with new lines, tabs)
This example shows how to use escape sequence in String Literals (Quoted values (single quotes) in WITH, SELECT or some other clause if driver supports). You can use @ symbol before string literal to allow special characters (e.g. /r /n /t /v /u0041 //).
SELECT * FROM rows
WITH
(DATA=@'{rows : [{id:1, name: "AA\u0041"},\r\n {id:2, name: "BBB"},\r\n {id:3, name: "CCC"}]}'
)Query Large Compressed File (From URL or Local disk)
This example shows how to read very large file from local disk or URL. You can read uncompressed or compressed file (in our example its GZip compressed file). Using –FAST option in your Filter enables Streaming Mode.
SELECT * FROM $
--LIMIT 10
WITH(
 Filter='$.LargeArray[*]--FAST' --//Adding --FAST option turn on STREAM mode (large files)
,SRC='zappysys-public-bucket/large_file_10k_largearray_prop.json.gz'
--,SRC='zappysys-public-bucket/large_file*.json.gz'
,IncludeParentColumns='False'  --//This Must be OFF for STREAM mode (read very large files)
,FileCompressionType='GZip' --Zip or None (Zip format only available for Local files)
)Query Simple 2D Array
This example shows how to query compact 2D array (array inside array) where column name is not repeated. You can specify Simple 2D Transformation along with filter to select column name (e.g. $.columns[*])
SELECT * FROM rows
WITH(
--enter path in SRC or use static value in DATA'
--SRC='zappysys-public-bucket/api/data.json'
--SRC='zappysys-public-bucket/some*.json'
--SRC='zappysys-public-bucket/somefile.json'
DATA='
{
  "columns": ["RecordID","CustomerID","CustomerName"],
  "rows": [ [1,"AAA","Customer A"], [2,"BBB","Customer B"], [3,"CCC","Customer C"] ]
}'
,ArrayTransformType='TransformSimpleTwoDimensionalArray'
,ArrayTransColumnNameFilter='$.columns[*]'
)Functions, GROUP BY, CASE, UNION, temp tables and more.
String Manipulation
This example shows how to use string functions. When you use function your entire dataset is first cached locally and then transformation is applied so you may notice some speed degradation.
SELECT
  substr('ZappySys', 1, 5)
, printf('%s %s %.2f', 'v1', CompanyName, CompanyId)
, ('Str1' || CompanyName || 'Str2') as ConcatExample
, upper('ZappySys')
, lower('ZappySys')
, replace('ZappySys', 'Sys', 'XYZ')
, instr('ZappySys', 'Sys')
, trim('   Zappy Sys  ') trim1
, trim('@@@ZappySys@@@', '@') trim2
, rtrim('    ZappySys   ')
, ltrim('    ZappySys   ')
, length( CompanyName )
FROM $ WITH (
FILTER='$.Info.Rows[*]',
DATA='{ Info: { Rows: [ { CompanyId: 1000 , CompanyName: "ZappySys" }, { CompanyId: 1001 , CompanyName: "Microsoft" } ] } }'
)Control flow
This example shows how to use math functions. When you use function your entire dataset is first cached locally and then transformation is applied so you may notice some speed degradation.
SELECT
	 COALESCE(10,20) coalesce1 --returns first non-null arg
    ,COALESCE(null,20) coalesce2 --returns first non-null arg
    ,COALESCE(null,20,30,40) coalesce3 --returns first non-null arg
    ,IFNULL(null,20) --returns first non-null arg. Same function as COALESCE but simple (just two arguments allowed)
    ,NULLIF(20,20) nullif1 --returns null if both argument same
    ,NULLIF(10,20) nullif2 --returns null if both argument same
FROM $ WITH (
FILTER='$.Info.Rows[*]',
DATA='{ Info: { Rows : [ { CompanyId: 1000 , CompanyName: "ZappySys" }, { CompanyId: 1001 , CompanyName: "Microsoft" }] } }')Date/Time
This example shows how to use date/time functions. When you use function your entire dataset is first cached locally and then transformation is applied so you may notice some speed degradation. JSON driver supports following 5 datetime functions.
SELECT
 DATE('now') date_now
,STRFTIME('%Y-%m-%dT%H:%M:%f','now') formatted_Date_time
,DATETIME('now') datetime_now
,DATE('now','localtime') datetime_now_local
,TIME('now') time_now
,JULIANDAY('now')
,DATE('now', 'start of month', '+1 month' , '-1 day' ) dt_modify1
,DATE('now', '+5 day') dt_modify2

FROM $ WITH (DATA='{ Info: { Rows : [ { CompanyId: 1000 , CompanyName: "ZappySys" }, { CompanyId: 1001 , CompanyName: "Microsoft" } ] } }')Math
This example shows how to use math functions. When you use function your entire dataset is first cached locally and then transformation is applied so you may notice some speed degradation.
SELECT
	 abs(-500)
    ,random()
    ,round(1000.236, 2)
FROM $ WITH (DATA='{ Info: { Rows: [ { CompanyId: 1000 , CompanyName: "ZappySys" }, { CompanyId: 1001 , CompanyName: "Microsoft" } ] } }')Pivot Value (Columns to Rows)
This example shows how to pivot column to rows (e.g. Transform property name as row value). By default Tag name (i.e. Property) outputs as Column name but when your column name is Dynamic then you can use Pivot Feature to transform the data.
SELECT
  Pivot_Name as ProjectName,
  Pivot_Value_id as Id,
  Pivot_Value_code as Code,
  Pivot_Value_budget as Budget
FROM $
WITH(
Filter='$.projects',
--enter path in SRC or use static value in DATA'
--SRC='zappysys-public-bucket/api/data.json'
--SRC='zappysys-public-bucket/some*.json'
--SRC='zappysys-public-bucket/somefile.json'
DATA='
{
  projects : {
    P101 : {id:1, code: "AAA", budget:1500.10},
    P102 : {id:2, code: "BBB", budget:7000.20},
    P103 : {id:3, code: "CCC", budget:1100.10}
  }
}
',
EnablePivot='True'
)JSON
This example shows how to use various JSON functions.
select
json_value(j1,"$.V1"),
json_array_first(j2),
json_array_last(j2),
json_array_nth(j2,1)
from array WITH (DATA=
'{"array" : [{"c1": "abc", "c2": "ABC", "j1": "{''V1'':''value1''}", "j2": "[13,22,''31'']"}] }')Run the same query from SQL Server or your own code.
SQL Server (linked server)
Query the driver from SQL Server through the Data Gateway. The driver does not have to be installed on SQL Server.
-- SQL Server: create a linked server to the ZappySys Data Gateway (here [ZAPPY_GATEWAY]),
-- then run the driver query through OPENQUERY.
SELECT *
FROM OPENQUERY([ZAPPY_GATEWAY], 'SELECT * FROM $
WITH (
    SRC=''zappysys-public-bucket/cust*-?.json''
    --,RECURSIVE=''True'' --Include files from sub folder
)')
C# (System.Data.Odbc)
using System;
using System.Data.Odbc;

// Use a DSN ("DSN=MyZappyDsn;") or name the driver directly
using (var conn = new OdbcConnection("DRIVER={ZappySys Azure Blob JSON Driver};"))
{
    conn.Open();
    var cmd = new OdbcCommand(@"SELECT * FROM $
WITH (
    SRC='zappysys-public-bucket/cust*-?.json'
    --,RECURSIVE='True' --Include files from sub folder
)", conn);
    using (var rdr = cmd.ExecuteReader())
    {
        while (rdr.Read())
        {
            for (int i = 0; i < rdr.FieldCount; i++)
                Console.Write("{0}={1}  ", rdr.GetName(i), rdr[i]);
            Console.WriteLine();
        }
    }
}
Python (pyodbc)
import pyodbc

# Use a DSN ("DSN=MyZappyDsn;") or name the driver directly
conn = pyodbc.connect("DRIVER={ZappySys Azure Blob JSON Driver};")
cursor = conn.cursor()
cursor.execute(r"""
SELECT * FROM $
WITH (
    SRC='zappysys-public-bucket/cust*-?.json'
    --,RECURSIVE='True' --Include files from sub folder
)
""")
for row in cursor.fetchall():
    print(row)
conn.close()
PowerShell
$conn = New-Object System.Data.Odbc.OdbcConnection
$conn.ConnectionString = "DRIVER={ZappySys Azure Blob JSON Driver};"   # or "DSN=MyZappyDsn"
$conn.Open()
$cmd = $conn.CreateCommand()
$cmd.CommandText = @'
SELECT * FROM $
WITH (
    SRC='zappysys-public-bucket/cust*-?.json'
    --,RECURSIVE='True' --Include files from sub folder
)
'@
$table = New-Object System.Data.DataTable
(New-Object System.Data.Odbc.OdbcDataAdapter($cmd)).Fill($table) | Out-Null
$conn.Close()
$table | Format-Table
Java (JDBC through Data Gateway)
// Java uses the ZappySys Data Gateway and the Microsoft SQL Server JDBC driver.
// On the gateway, add a data source (here "MyZappySource") that uses the ZappySys Azure Blob JSON Driver.
import java.sql.*;

String url = "jdbc:sqlserver://localhost:5000;databaseName=MyZappySource;user=MyGatewayUser;password=MyPassword;encrypt=false";
String sql = "SELECT * FROM $\n"
           + "WITH (\n"
           + "    SRC='zappysys-public-bucket/cust*-?.json'\n"
           + "    --,RECURSIVE='True' --Include files from sub folder\n"
           + ")";
try (Connection conn = DriverManager.getConnection(url);
     Statement st = conn.createStatement();
     ResultSet rs = st.executeQuery(sql)) {
    while (rs.next()) {
        System.out.println(rs.getString(1));
    }
}
PHP (odbc_connect)
<?php
$conn = odbc_connect("DRIVER={ZappySys Azure Blob JSON Driver};", "", "");   // or "DSN=MyZappyDsn"
$sql = <<<'SQL'
SELECT * FROM $
WITH (
    SRC='zappysys-public-bucket/cust*-?.json'
    --,RECURSIVE='True' --Include files from sub folder
)
SQL;
$rs = odbc_exec($conn, $sql);
while ($row = odbc_fetch_array($rs)) {
    print_r($row);
}
odbc_close($conn);Articles
Guides and tutorials for the Azure Blob Driver for JSON Files
Compatibility and requirements
Built for Windows, and for your own environment.
- Windows 11, 10, 8 and 7, and Windows Server 2022, 2019, 2016, 2012 R2 and 2008
- .NET Framework 4.x. The JDBC Bridge Driver also needs Java 8 or later
- 32-bit and 64-bit ODBC drivers. SQL Server 2012 through 2025 through the Data Gateway
- Self-hosted: drivers run in your Windows process, business data does not pass through ZappySys servers, and credentials stay in your DSN
- Free trial of ODBC PowerPack: test with your own data before you buy
FAQ
Questions about the Azure Blob Driver for JSON Files
Which tools and languages can use this driver?
Any ODBC-compliant tool, such as Power BI, Tableau, Qlik, SSRS, Informatica, Excel and SSIS. You can also connect from Java, C#, Python, PowerShell and other languages with an ODBC connection string.
Do I need to install the driver on SQL Server?
No. With the Data Gateway option the driver runs on the gateway machine and SQL Server connects to it through a linked server.
Which edition includes the Azure Blob Driver for JSON Files?
The Azure Blob Driver for JSON Files is included in the Professional and Enterprise editions of ODBC PowerPack. See the edition comparison for the full list.
Can I query many files, or compressed files?
Yes. Use a wildcard in SRC, add RECURSIVE='True' for sub-folders, and set FileCompressionType to GZip or Zip.
Can I save a query to reuse it?
Yes. Save a query as a virtual table or a stored procedure (custom objects) in the DSN. Tools then see it like a normal table, and a procedure can take parameters. See custom objects in ODBC drivers.
Is there an SSIS version?
Yes. This driver uses the same data engine as the JSON Source in SSIS PowerPack.
Which SQL Server and Windows versions are supported?
Support for SQL Server 2025, 2022, 2019, 2017, 2016, 2014 and 2012 (32/64 bit) through the Data Gateway. See the system requirements.
Can I try it before buying?
Yes. Download ODBC PowerPack, create a DSN and test your own data before you buy.
Related drivers
Pair it with the rest of ODBC PowerPack.
 Azure Blob Driver for CSV FilesQuery CSV blobs from Azure Blob Storage.
 Azure Blob Driver for XML FilesQuery XML blobs from Azure Blob Storage.
 JSON / REST API DriverQuery JSON files and REST APIs with SQL, OAuth, pagination, and streaming for la
 Amazon S3 Driver for JSON FilesQuery JSON objects stored in Amazon S3 buckets.
 FTP / SFTP Driver for JSON FilesQuery JSON files over FTP, FTPS, or SFTP.
 Data GatewayInstall once on any server. All client apps connect to it — no ODBC on every mac
What customers say
Start your free trial today
Install ODBC PowerPack and add a Azure Blob Driver for JSON Files DSN.
Preview your data in the driver UI before you connect your tool.
- One DSN, many toolsPower BI, Excel, SSIS, Python and SQL Server can all use it.
- Free trialTest the driver with your own data before you buy.
- Live supportHelp during your trial and after purchase.
Open Help FileBrowse all ODBC PowerPack drivers
New purchases may be eligible for refund review within 30 days. See the refund policy.
Talk to an engineer before or during your trial.